What a Machine-Readable Tone Guide Contains
Effective tone guides replace vague adjectives with testable rules and behaviors.
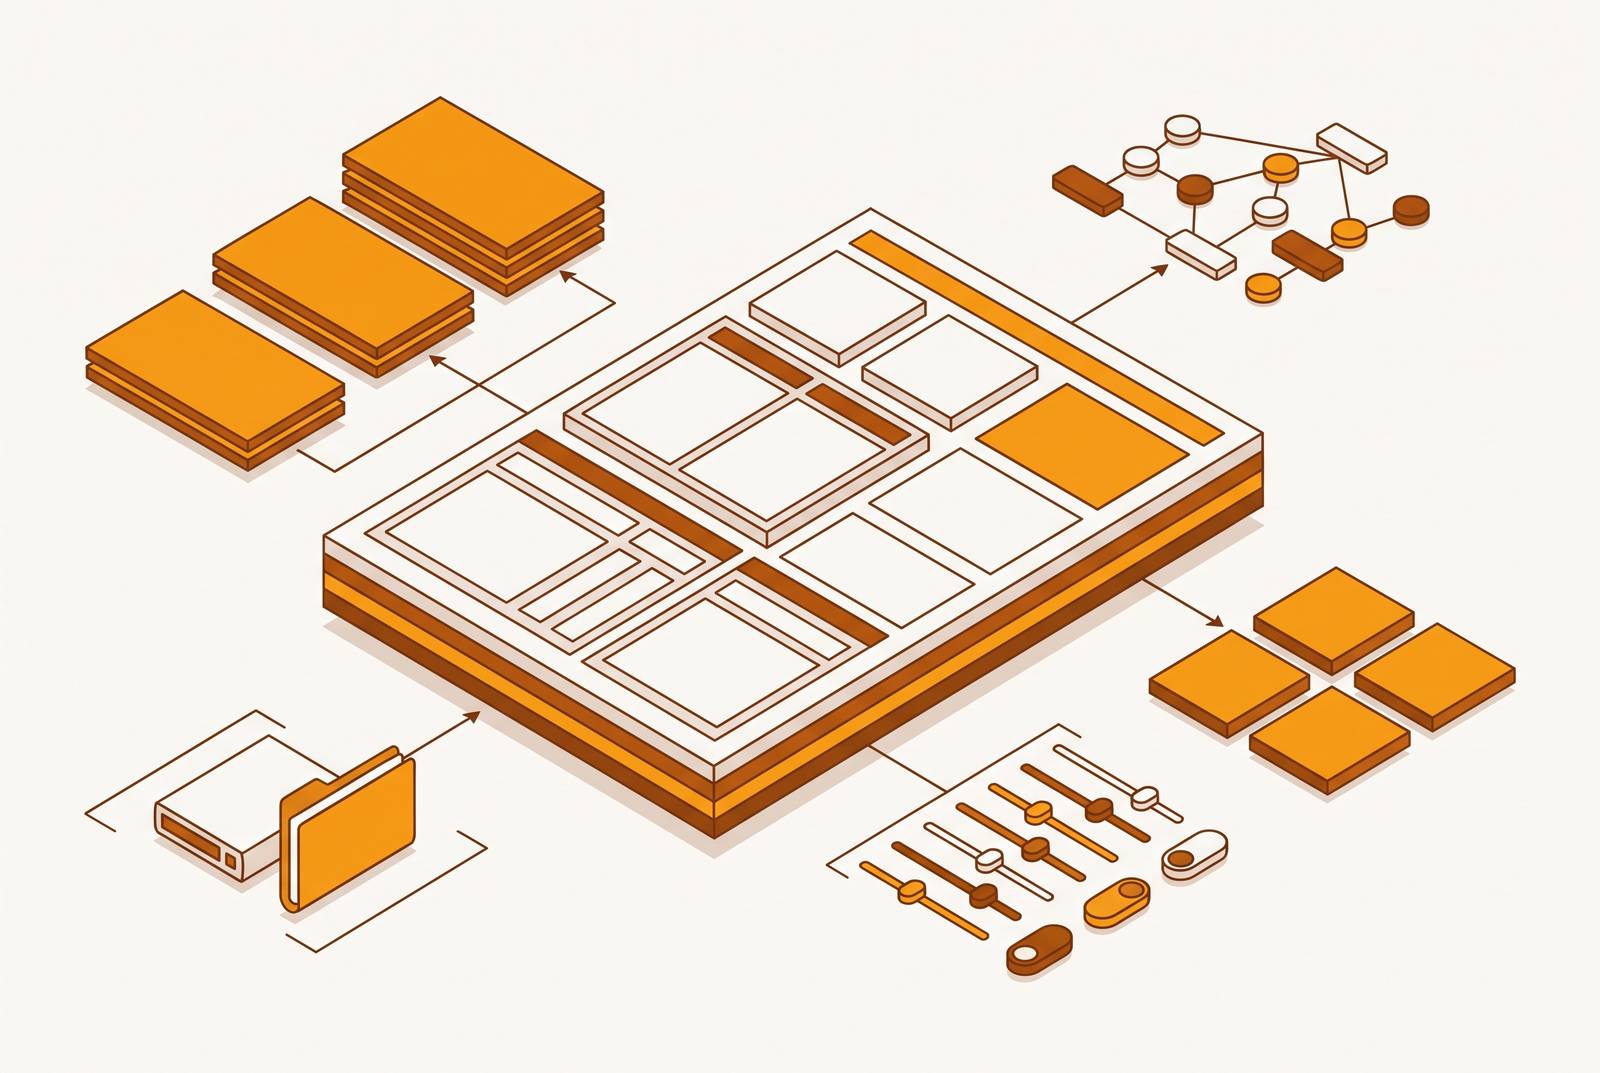
A machine-readable tone guide replaces adjectives with decisions.
A tone guide built for language models replaces adjectives with decisions. Each rule needs three parts: a condition that tells the model when it applies, an action that tells it what to do, and a failure state that makes the rule checkable against an actual draft. Sentence architecture becomes a target word count, vocabulary boundaries become a named preferred term and a named banned one, and rhythm gets written as a behavioral principle a reviewer can apply to a paragraph and judge correctly. Adjectives like "warm but authoritative" carry no sentence length, no vocabulary, no rhythm the model can execute against, so they produce only a guess.
Why adjective-based tone guides fail with a machine reader
Tell a copywriter to sound "warm but authoritative" and the copywriter knows what to do with it. The phrase calls up years of reading, a sense of who the brand is, maybe a mental image of a specific competitor to avoid sounding like. A model has none of that. Feed the same instruction to a language model and it has no sentence length to target, no vocabulary to favor, no rhythm to match. It can only guess.
The guess is not random. Converting the brand PDF into a JSON file does not fix this. The failure sits one level below file format. Traditional brand books lean on shared context, cultural fluency, and the kind of judgment calls a human picks up from experience, and a model has none of those capacities built in. An AI image generator needs the same idea spelled out as a named subject, a composition, a palette given in hex values, and an explicit list of what not to include. The gap between those two readers is the whole problem this piece is about.
What "machine-readable" requires from a tone rule
A machine-readable tone rule is not a sentence describing a personality. It functions as a small decision: something triggers it, something follows from it, and something would count as getting it wrong.
Each rule needs three parts to do its job: a condition that tells the model when the rule applies, an action that tells it what to do, and a failure state that tells it, or a reviewer, when the rule has been broken. Leave out that third part and there is no mechanism left for checking a draft against the rule. It just sits there as a suggestion.
Rules also need to exist as separate, named pieces. A tool mid-draft should be able to pull the vocabulary list without also loading the color palette or the competitive positioning statement. That kind of granularity is what makes selective retrieval possible later on, and it only works if each rule was written, from the start, to stand alone.
None of this is a technical afterthought bolted onto writing that was already finished. Building a rule this way is a writing discipline first. The file format comes last, and it's the smallest part of the job. A rule that is retrievable as its own unit, executable because it names an action, and checkable because it names a failure state, that is the basic unit every component in this piece is built from.
What should replace adjectives like "warm but authoritative" in the voice layer of a tone guide?
Voice has to be written down as a set of behaviors, not a set of adjectives, because a model can carry out a behavior and cannot carry out a feeling. "Confident" is not executable. "Average sentence length of 14 words, with occasional four-word sentences for emphasis" is.
Sentence architecture is the clearest place to start. A principle that a reader cannot apply to an actual sentence has not been specified closely enough to use.
Take a vague version: "Write with confidence." Now the executable version: "State claims directly. Avoid hedges like 'might' or 'could potentially.' Before: 'This approach might help reduce costs for some customers.' After: 'This approach cuts costs.'" The second version gives a model something to check a draft against. The first one does not.
Vocabulary boundaries work the same way. A rule stating "use 'adviser' (preferred); never 'clients'" is checkable, word by word, against any draft. A rule stating "use professional language" is not checkable against anything. Banned-phrase lists belong in this layer as enforcement tools, setting the floor a draft cannot fall below, not as a stylistic footnote tucked at the end of a style memo. An "AI Tell" list like this gives anyone reviewing machine-generated drafts the fastest possible check for whether the output still sounds like the brand or has slipped into generic model output.
Rhythm and stance round out the layer. Three to five behavioral principles is the right number for this whole layer. Any more and the list stops being checkable in practice. Each principle should pass a simple test: hand a paragraph to a person and see if they can say, correctly, whether the rule was followed. A rule nobody can judge that way has not been written tightly enough yet.
The narrative identity layer: positioning, audience, and competitive stance as structured fields
Most tone guides stop at visual identity and a paragraph describing tone. What is missing is a layer that defines who the brand is for, who it is deliberately not for, the kind of work it refuses to take on, and what it believes about the market that its competitors do not say out loud.
This layer should exist as separate fields, each retrievable on its own: a positioning statement, an ideal customer profile that includes disqualifiers, a stated competitive truth, and a set of proof points backing it up. Each field carries one decision, the same granularity principle from the rule's anatomy, applied here to the brand's identity.
The disqualifiers matter as much as the description of who the brand serves. Tell it who the brand explicitly does not serve, and the boundary becomes something the model can check a draft against.
Competitive stance needs the same treatment. If the belief that sets the brand apart from its category never makes it into a structured field, the model falls back on the kind of generic reassurance any company in the category could make. Picture a model drafting a renewal email on a Tuesday afternoon. It needs more than an instruction to sound "customer-centric." It needs to know what the company actually claims about itself that a competitor would not claim, and it needs that claim sitting somewhere it can retrieve at the moment of writing, not buried in a slide deck from a strategy offsite two years back.
Brand infrastructure platforms add real value at exactly this layer. Platforms like Rainbrand take in a brand's existing materials, websites, decks, internal files, and turn that material into brand identity and guidance that sits as retrievable context any connected agent can query at the moment it needs it. That beats the alternative, which is every team member reconstructing the brand's positioning from memory or from whatever static PDF happens to be the latest one somebody remembers to update.
Scenario-conditional tone rules: encoding context-switches the model will not infer
Human writers shift register without thinking about it. Write to a frustrated customer in the morning and a prospective partner in the afternoon, and the shift happens automatically. A model does not have that instinct, and it needs the switch written out as an explicit if-then instruction for every context change the brand can predict in advance.
A healthcare brand offers a clean example. Write the switch as a conditional and it becomes something a system can execute reliably: "If prompt references clinicians, use formal, evidence-based tone. If prompt references patients OR mentions appointment scheduling, use warm, accessible tone." That is the level of explicitness this layer requires: a condition on the left, an instruction on the right, no inference required in between.
The same structure governs the tension between creative freedom and strict compliance. A creative tool might run on loose parameters that leave room for exploration. A hybrid tool allows variation but only within defined guardrails. Each of those three modes needs its own trigger condition spelled out, because a model has no way to know which mode it is operating in unless the prompt or the system tells it.
Format rules belong here too, not in the voice layer discussed earlier. Written out this way, the full set of scenario rules becomes a finite list. That list can actually be audited. Auditing that list is work for whoever governs the brand's AI usage, not a task left to whoever happens to be writing the prompt that day.
Annotated examples: why unmarked examples are worse than no examples
An example that is labeled teaches faster than any adjective could. An example with no label attached can actively mislead, because the model reading it has no way to tell whether that older piece of copy is something to copy or something to avoid.
Every example in the guide needs a clear tag: on-brand, off-brand, or situational. That classification does the real work. It is not a cosmetic label stuck on afterward, it is itself the instruction. Pasting a strong piece of copy into a document without saying why it's strong tells a model nothing it can generalize from.
Take an unannotated drop: a paragraph of old marketing copy, pasted in with no comment, under a heading that just says "Example." A model reading that has to guess what made the paragraph work, if anything did. Now annotate the same paragraph: "On-brand. Opens with a direct answer, not a question. Sentences run eight to twelve words. Uses contractions throughout. The word 'simply' appears twice and is one of the words that makes this recognizably ours rather than a competitor's." The annotation does the teaching the raw example could not do on its own.
One cause of bad example selection is picking a piece of copy because it performed well. Performance is a signal to note when building the set, not proof that a given example represents how the brand writes day to day.
Format specifications and output patterns as first-class fields
Output patterns are the part of the guide a model can actually check itself against. It can count the words in a headline and confirm it stays under eight. It has no way to confirm that the headline "feels premium," because that judgment was never given to it as something countable.
Fields like these produce consistent, brand-safe output across every place the brand shows up, without requiring a human to review each individual response before it goes out.
Visual prompts need the identical treatment. An AI image generator cannot do anything useful with a mood description. A reference specification removes the ambiguity that a phrase like "moody and premium" would otherwise leave behind.
These format fields should be sorted by content type and channel rather than stored as one global specification covering everything at once. A social post and a whitepaper call for different rules, and that is exactly the conditional structure built out in the scenario section: it keeps format rules from colliding with each other once a model has to apply more than one at a time. Treated this way, format specs function as enforcement, the same checkable floor a banned-word list sets for vocabulary, not a style preference floating loose in the document.
Serving the guide: named units, versioning, live retrieval
A tone guide sitting in a PDF or a shared Drive folder is not machine-readable in any way that matters operationally, no matter how well it is written. Machine-readable means a model or a tool can query the guide at the exact moment it is generating something, not that the guide is legible to a person who opens the file.
Naming each unit separately, one decision per unit, is what makes this kind of retrieval possible. A tool partway through drafting a response can pull just the vocabulary list without loading the entire guidelines document alongside it, which matters for keeping token use down and matters just as much for keeping the context precise.
Versioning is what keeps any of this trustworthy over time. Brand context that goes stale or turns out wrong, once it's sitting in a source machines pull from automatically, ends up directly inside AI-generated responses sent to real customers. That risk means brand context has to be treated the way a codebase treats its dependencies: versioned explicitly, updated in one place, and propagated downstream to every connected tool without someone having to manually push the change everywhere it's used.
The Model Context Protocol, known as MCP, is the standard making this kind of live retrieval workable at scale. Rainbrand's Brand Skill architecture applies this same model directly to brand identity: a brand's materials get ingested once, exposed afterward as versioned context retrievable through an API or through MCP, so every connected agent or product picks up the latest version automatically, with no team manually re-pasting guidelines or reconfiguring a tool by hand.
The same criterion now separates platforms built for this job from platforms that only display guidelines well. Rankings of brand guideline platforms by AI-readiness as of July 2026 weight machine-readable delivery, meaning MCP, structured markdown, or API access, as the single highest-scoring criterion. That ordering reflects a real distinction: showing guidelines clearly to a person and delivering them reliably to a machine are two different capabilities, and most platforms on the market today were only ever built for the first one.
GuideBrand Voice Examples: Six Voices Written So People and AI Can Use Them