Translating Legacy Brand Guidelines Into Structured Voice Specs
How to convert vague brand language into AI-ready voice rules.
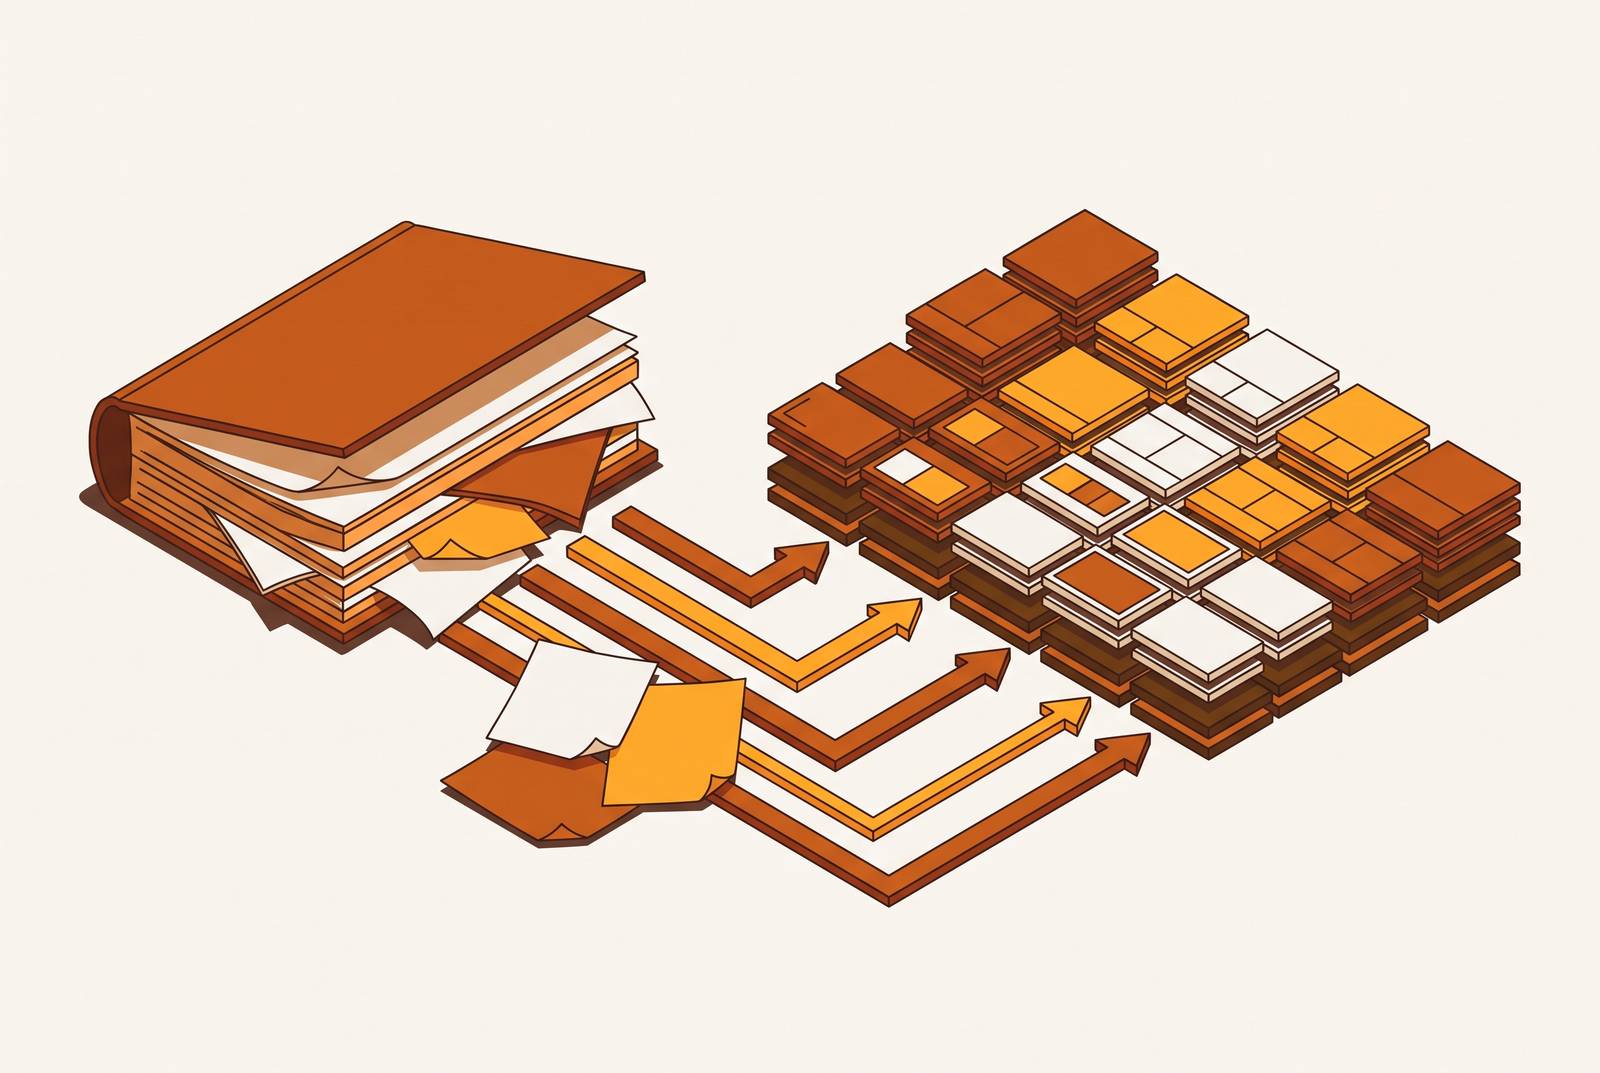
Translating legacy brand guidelines into structured voice specs means replacing language that asks for interpretation with rules that guide generation. The goal is a retrievable, versioned system of behaviors, tone settings, vocabulary, syntax, evidence standards and examples that lets AI agents produce a distinct brand voice.
Why legacy voice guidelines fail as AI inputs
Traditional guidelines rely on judgment that the document itself does not spell out. A human author brings professional experience to the instruction “confident and conversational” and interprets it in the context of the brand. A model instead draws on the aggregate meaning of those words in its training data. The adjective leaves the central decision unresolved, namely what confidence sounds like for this particular company. Generic output follows from that gap between intent and instruction.
The practical test is whether a new author or an AI assistant could use the guide without needing heavy rewrites. If not, the guide has not made the brand’s choices explicit enough. Adding more pages does not necessarily fix that weakness, because competing information can dilute the influence of individual rules. The bottleneck is no longer generating enough content but making that content recognizably specific. The conversion therefore has to change the structure of the guidance.
What a structured voice spec actually consists of
A structured voice spec has seven components, each with a separate job. Its personality core defines observable behaviors, while its tone scales define how those behaviors adjust to context. Vocabulary use-and-ban lists govern word choice, and structural and syntax rules govern the shape of the writing. Proof and evidence standards govern how claims are supported, while a purpose statement establishes what the writing is meant to achieve. Annotated writing samples show these rules working together in finished text.
Personality comes first because the other components need a stable account of how the brand behaves. Tone, vocabulary and syntax then make that account increasingly concrete. Evidence standards and purpose keep those choices tied to what the content needs to say as well as how it sounds. The examples provide the final test of whether the components agree.
Company-level voice stays constant across channels and teams, while campaign-level style makes limited adjustments. Within those boundaries, the spec should cover the formats the team produces most often, including blog posts, product announcements and customer emails. Each needs applicable behavioral rules rather than an undifferentiated universal instruction. Otherwise, the language of a campaign can become a lasting brand rule by accident.
Converting personality adjectives into behavioral constraints
The foundational move is to turn each personality trait into something visible in the output. “Confident” becomes active voice, an answer-first opening and outcomes stated before methods. These instructions tell the model what to do with a sentence by making the disposition explicit. They also give a reviewer a clear basis for judging compliance. A trait becomes useful when its presence or absence can be identified in the text.
Keep the personality core to three to five traits so that it does not become a set of competing demands. Each trait needs positive behaviors and a negative constraint that defines what the brand does not sound like. For confidence, the positive instruction to state the answer can be paired with a ban on unnecessary hedging. That boundary often does more to block generic output than another adjective describing the brand. The task is to preserve the trait’s meaning while removing the need to guess how it should appear.
Zapier’s publicly released Brand Guidelines Builder skill offers a brief example of the operational direction. It works in Cursor, Claude Code and other agents, bringing brand-guideline work into the tools where people act on it. That is distinct from claiming that Zapier embedded AI instructions in its own internal guidelines.
Building tone scales that give models numerical anchors
Personality defines the stable behaviors, but tone determines how they adjust to a situation. Numerical tone scales make that adjustment explicit rather than leaving it to the model’s interpretation of a content type. Each dimension needs an anchored scale and a setting for the relevant format. The model can then hold the personality rules steady while changing the specified tone settings. The numbers serve as reference points alongside descriptions of what each setting means.
Formality, energy and directness need separate dimensions because they do not move together. A configuration can have low formality, high energy and very high directness without contradiction. Reducing those choices to a single formal-to-casual spectrum discards that distinction. It also makes the setting less informative, because it does not say which aspect of the writing should change. Independent scales preserve the brand’s combination of traits while allowing controlled variation.
Map those configurations to specific content types, including a product launch email, an error message and a support reply. The instruction specifies which dimensions change, where their numerical anchors sit and which personality behaviors remain fixed.
Writing vocabulary lists and anti-pattern rules the model can actually retrieve
Vocabulary is the most directly enforceable layer because it can specify exact choices. A use list can establish “members,” not “users,” while a ban list can exclude “best-in-class,” “innovative” and “in today’s digital landscape.” These entries remove ambiguity at the point of word selection. They are also straightforward to retrieve without interpreting a broader personality description. The ban list often does more immediate work because it blocks phrases the model otherwise defaults to.
Extract this vocabulary from content that already sounds most like the brand. Samples from different teams and formats help distinguish shared language from one author’s habits. Signature phrases belong in the same layer as the positive counterpart to prohibited language. Annotating what each sample does right makes the extraction deliberate. The existing content supplies the patterns, and the spec makes them explicit.
Anti-pattern rules extend the vocabulary layer from enforcement to diagnosis. They identify not only an unwanted phrase or construction but also the constraint its appearance suggests was ignored. That helps a reviewer trace a flaw that keeps coming back to a rule that needs to be clearer. For high-stakes touchpoints, including pricing, guarantees, comparisons and sensitive topics, canonical one- or two-sentence templates provide a stricter boundary. Where the spec requires those templates verbatim, stylistic variation is not an acceptable substitute.
Specifying rhythm and syntax so sentence-level patterns hold across outputs
Approved vocabulary cannot by itself reproduce the way a brand builds sentences. Rhythm rules must also define sentence-length preferences, the use of fragments, active or passive voice and whether sentences may begin with “And” or “But.” Rhetorical questions need an explicit rule, including whether they can open a piece. Without them, the right words can still appear in writing that feels unlike the brand.
The move from “our tone is direct” to “Open with the answer, not a question.” replaces an aspiration with an instruction that controls the opening’s form. Likewise, the supplied contrast between “we believe” and “we’ve seen” shows how a small construction changes the force of a claim. Evidence standards must govern whether the stronger wording is justified, however. Even when a voice rule favors a construction, the content still needs evidence to imply that something was observed.
Cadence also needs to vary by format. The rhythm rules for social posts, ad copy and email subject lines need to differ from those for blog posts and whitepapers. For long-form work, the spec must cover paragraph length, transitions and section openings, where generic patterns can become especially conspicuous. Point of view belongs here too, with explicit rules for first person, second person or brand voice. Together, these rules keep the sentence-level pattern steady even when the subject and vocabulary change.
Building the annotated example set that anchors every other rule
Annotated examples are the spec’s proof-of-concept layer. Models pattern-match on examples more reliably than they follow abstract guidance, so the samples must demonstrate the intended result. For long-form content, the set needs enough carefully polished text that sounds like the brand for the model to pick up those patterns. Quantity matters only when the material is suitable.
Each sample should have a short note that names the personality behavior, tone setting and rhythm rule it shows. That annotation explains why the sample belongs, allowing a model or reviewer to connect the result to the instruction. It also makes conflicts visible when an approved example does not match a written rule. Samples from different teams and formats keep the target broader than one person’s style. The material needs to be current and accurate because an old landing page can teach out-of-date positioning as easily as useful cadence.
Annotated bad outputs should identify the violated rule and explain why the result is wrong. This gives the model a diagnostic as well as a target, while giving reviewers language for corrections. With those samples in place, the purpose, evidence standards and behavioral rules can be judged together in actual writing.
Storing and retrieving the spec so agents can actually use it at runtime
A structured spec stored only in a shared drive still depends on someone remembering to supply it. The operational requirement is a versioned resource that connected agents and workflows can retrieve at the moment of generation. Manual copying into individual prompt sessions separates the source from its downstream uses and makes changes harder to propagate. Retrieval therefore needs to be built into the spec as well as used to share it.
MCP, or Model Context Protocol, has an interface with three parts that matter here. Resources are data an agent can read, addressed by URI, while tools are callable functions with typed schemas. Prompts are reusable templates. A structured voice spec fits directly into the resource part, putting brand instructions in a context that is spelled out and managed. The interface supplies a way to access that context, but useful access still depends on describing it clearly.
The paper “Model Context Protocol (MCP) Tool Descriptions Are Smelly!” found that most analyzed tool descriptions failed to state their purpose clearly and nearly all contained at least one quality issue. That finding makes the description of the brand resource consequential. The agent needs to understand what the resource is for if it is to retrieve and apply it appropriately. Where retrieval is exposed through the tool layer, that description belongs within the spec’s operational scope. Structure alone is not enough if the entry point is unclear.
Claude Projects, ChatGPT Custom Instructions and Cursor’s .mdc files in .cursor/rules are lightweight entry points. MCP-native storage gives teams that run multiple agents across multiple brands an option built for that infrastructure. The deciding requirement is not simply where the text resides but whether changes can reach its downstream uses without manual prompt-by-prompt updates. Version control and propagation turn the spec from a stored document into a maintained resource.
Maintaining the spec as the brand voice evolves
The strongest objection to encoding voice is that it could preserve the brand’s past too rigidly. That risk is real when the spec is treated as finished, and it is an argument for versioning explicit rules. Julia Jaskólska, Brand Design Lead at Zapier, frames brand less as a static guideline and more as a shared mental model. Clear intent lets teams move without losing direction, while vague intent gives AI more vagueness to amplify.
Define review triggers so that evolution does not depend on someone noticing drift. A new product line, a repositioning or campaign language selected for continued use can each prompt a review. The resulting change belongs in one versioned source so that downstream agents inherit the same direction. Temporary campaign adjustments should become permanent voice rules only through that deliberate decision.
People still need to judge the writing even when AI quickly gets it roughly on-brand. The workflow is AI drafts, human directs, and the spec changes when a correction reveals a gap. That final judgment covers both whether the writing sounds right and whether it quietly contradicts positioning. A living voice spec does not freeze the brand into a document but puts its evolving rules inside the toolchain as infrastructure.
GuideBrand Voice Examples: Six Voices Written So People and AI Can Use Them