What to Actually Watch When Monitoring AI Output for Brand Consistency
Monitor how AI consistently applies voice, visuals, and audience fit—not just spelling and logos.
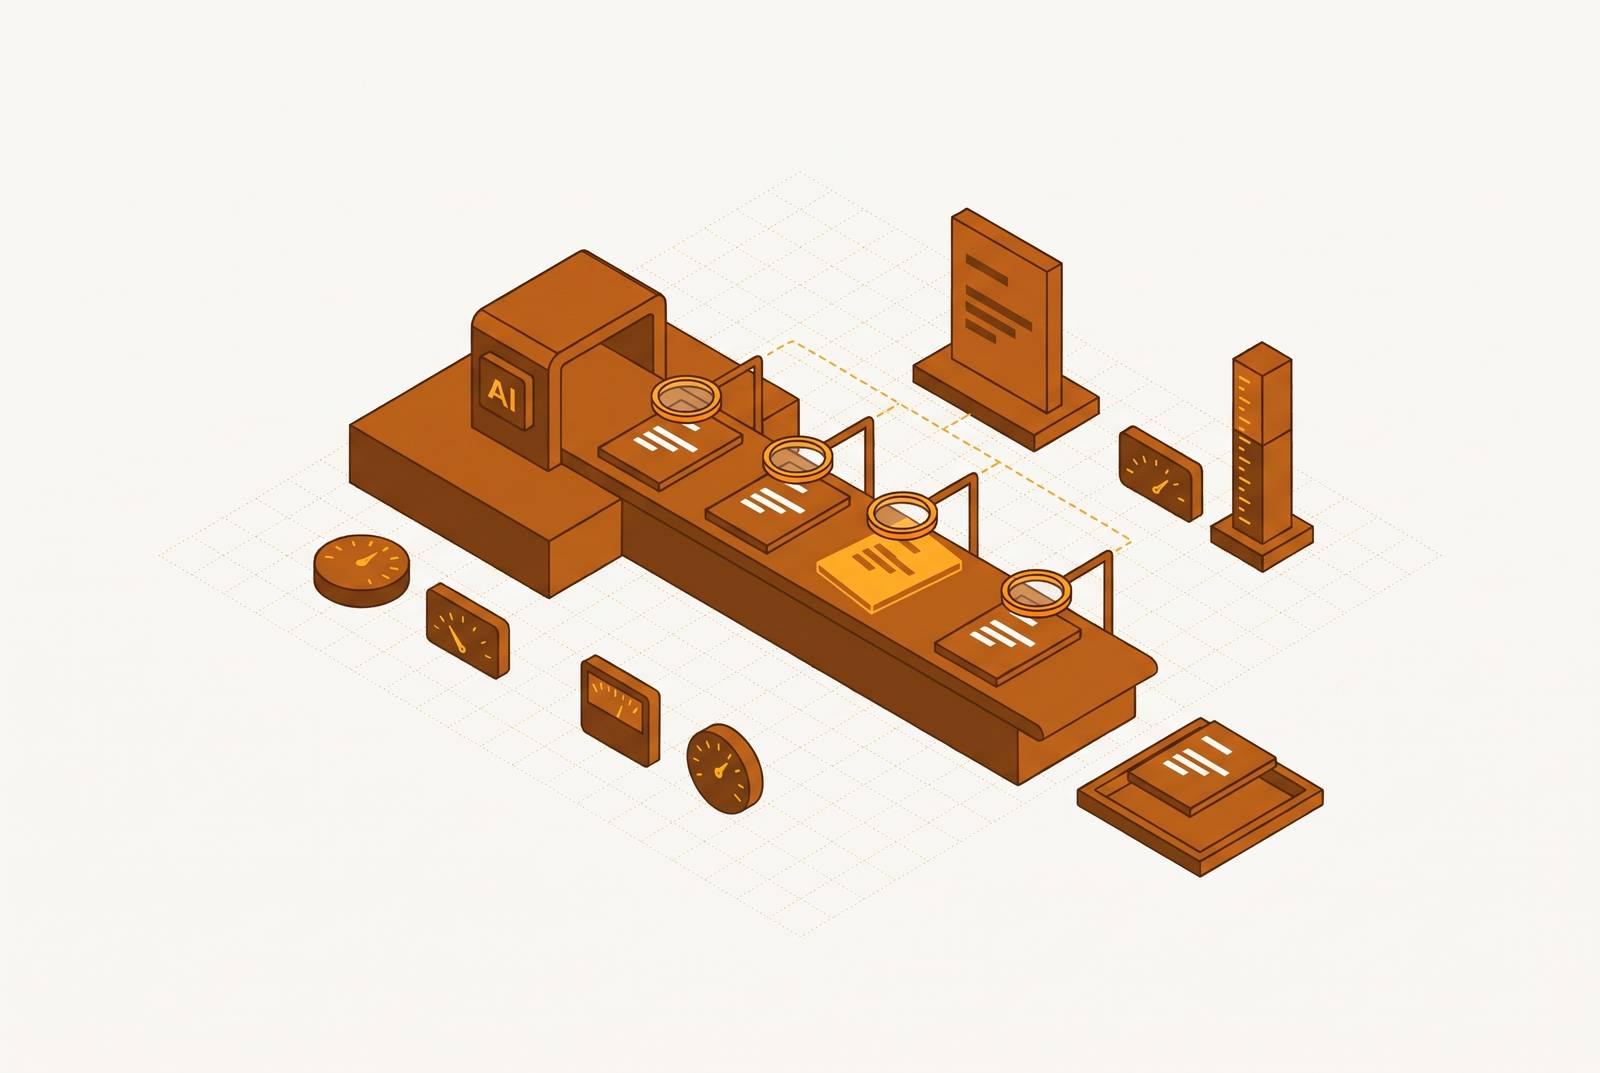
To detect when AI output drifts off-brand, check voice, visual identity, and context fidelity against a structured brand reference. Correct spelling, colors, and logos cannot establish whether an agent understands the brand or the task. Effective monitoring checks the choices within each output and the context shared across production steps, then uses findings to improve that context.
Why monitoring AI output for brand consistency is harder than it looks
A product name can be spelled correctly while the surrounding copy misrepresents its positioning. A tagline can use approved words in the wrong register, and an image can contain the right palette while expressing the wrong mood. These outputs pass narrow checks because those checks test individual features in isolation from the brand meaning that connects them.
The underlying failure is often context deprivation. Without authoritative brand context, an agent generates from training data rather than the brand’s approved style, actual guide, or purpose. Each session can therefore begin cold, with no memory of earlier approvals. The result may be polished and readable while sounding like a competitor.
A QA agent can check brand guidelines, resolution requirements, platform specifications, and legal compliance rules only when those requirements are available as usable inputs. A PDF in a shared drive does not, by itself, supply that reference. Useful monitoring therefore needs a structured set of signals that exposes whether the agent is applying brand context or filling its absence with plausible choices.
Voice drift: how AI output loses brand personality before anyone notices
When brand context is missing, voice often defaults toward a generic marketing register. Copy becomes enthusiastic, vague, and punchy without retaining the cadence or perspective that distinguishes the brand. The change can be gradual enough that each passage seems acceptable on its own. The sentences themselves may be free of errors. The loss becomes apparent in the relationship between the output and the brand’s established way of speaking.
Sentence structure is one observable indicator of that loss. A brand built around clipped, direct statements differs from one that develops ideas through expansive explanation. An output can preserve the topic while abandoning that rhythm. Vocabulary is another sign, especially when the brand has set out product-specific terms, owned phrases, or words to avoid. A made-up synonym may read smoothly but take the place of a term the brand has chosen to express its positioning.
Point of view and register reveal a different failure. Copy may discuss the right product while addressing a generic category audience rather than the customer the brand actually speaks to. It may also address that customer with the wrong degree of formality or enthusiasm. A passage can be accurate and easy to read while failing both.
Because these distinctions depend on established patterns, a one-line instruction cannot reliably convey them across tasks. A description of the desired tone leaves room to guess at cadence, terminology, and the relationship with the audience unless structured guidance stays available across tasks. A reviewer’s sense that copy sounds acceptable is not the same as evidence that it matches the brand. Detection requires a reference standard against which those choices can be compared.
Visual signal drift: what changes in images before the logo does
Before a logo becomes visibly wrong, assets can move away from the brand through mood, composition, and stylistic choices. The practitioner term “style creep” names this less obvious shift across a campaign. Each image may look good on its own while the images as a group lose their shared visual identity. Technical polish does not establish visual alignment.
Mood and atmosphere expose whether an image belongs to the brand’s world rather than merely illustrating the requested subject. Compositional conventions make that assessment more specific. A brand may favor negative space, a particular subject position, or a consistent way of framing its product. Changes in those conventions are observable even when the palette remains correct. Color application adds another distinction because the presence of approved colors does not establish that their proportions and uses match the brand.
Typography and mark integrity provide more directly checkable signals. Text within generated images can contain distortion or substitution, while logos can show warping, missing elements, or pattern changes. These defects differ from a judgment about mood. They concern identifiable elements that fail an explicit requirement. Monitoring both kinds of signal prevents aesthetic review from replacing technical checks, or technical checks from standing in for aesthetic review.
The structural difficulty is that most image-generation tools lack a persistent place to retain what a particular brand looks like. Each session reinterprets a text description, allowing variation into choices that should remain consistent. Visual identity includes the relationships among color, composition, mood, typography, and marks.
Context fidelity: whether agents understand what they are making and for whom
Even accurate voice and close visual alignment can conceal a deeper failure. An agent may produce work that looks and sounds appropriate but serves the wrong audience, channel, campaign moment, or product positioning. Context fidelity concerns whether its choices match the purpose of the brief. Plausibility is not enough to establish that match. The output needs to reflect the decisions the brand team would make for this particular task.
Audience calibration is one way to examine that relationship. Output pitched to a generic customer in the category can miss the brand’s actual customer without containing an obvious factual error. Channel appropriateness tests a separate choice. A LinkedIn post and a paid display ad are not interchangeable simply because both use approved language and imagery. Repurposing one for the other without adjustment can preserve brand features while losing the intended use.
Product and messaging accuracy require more than getting the product name right. They include its positioning, differentiators, and current messaging, which category-generic claims can obscure. Campaign coherence then asks whether the work fits the campaign it belongs to or could appear in any campaign. These criteria distinguish task alignment from general brand resemblance. An asset can satisfy the latter while failing the former.
This problem gets worse when no single agent has the full brief. Each agent may complete its assigned slice without access to the purpose that connects the work. Getting agents to work together across content operations does not, on its own, give them that shared understanding. Context fidelity cannot be monitored without a structured brief that defines what the work is for, whom it addresses, and where it belongs.
Why multi-agent pipelines create compound drift that single-output review misses
In a multi-agent pipeline, small deviations can compound across handoffs. One agent writes copy, another generates images, and another adapts the work for channels. If each operates from a different interpretation of the brand, no individual step has to look obviously wrong for the assembled campaign to become inconsistent. Failures in voice, visual identity, and context fidelity become linked, so they need to be reviewed together.
Shared context is not automatic in these workflows. Short-term agent memory is transient by default, although explicit shared memory mechanisms can provide persistent context. Without them, the agents may begin from separate interpretations of the same brief. The handoff also loses the human judgment that might otherwise catch a mismatch between steps. Completing the assigned task does not establish that the next agent receives a coherent understanding of it.
When the same agents work across different clients, the absence of brand-specific context creates a risk of cross-contamination. One client’s visual conventions can enter another client’s output. This is a failure to keep distinct reference standards separate as work moves through the system.
Final-output review can identify the inconsistency that survives production, but it cannot by itself reveal where the deviation began. That makes correction harder because the visible defect may originate before the step that produced the final asset. Guidelines therefore need to remain a reference from brief intake through generation and QA. Pipeline-level monitoring must examine the context available at those steps as well as their outputs.
What a structured brand context layer looks like as the monitoring baseline
The practical prerequisite is a reference standard that agents can consume and apply. A human-readable brand guide leaves the reader to work out what its descriptions and examples call for. A structured brand context layer turns those expectations into clear parameters that agents can access when they generate and review work. Making a document available does not necessarily make its requirements queryable.
For voice, that layer includes tone parameters, vocabulary rules, owned phrases, and register by channel. For visual identity, it has color values and rules for how to use them, type specifications, and approved imagery styles and moods. These parameters give reviewers something more precise than a broad description of personality. They also distinguish a requirement from an interpretation, which is essential when multiple agents generate related outputs.
Messaging context sets out the positioning, differentiators, who the audiences are, and the current campaign themes. The structured brief then adds the task-specific purpose, audience, and channel. Together, they provide the baseline for context fidelity checks. General brand rules establish what remains consistent across work, while the brief establishes what this particular piece must accomplish. Neither can replace the other.
A shared knowledge base is the operative mechanism behind consistent monitoring. Agents connected over an open protocol like MCP can query a single, current brand context layer. The protocol provides a way to access a reference that still needs to be defined. Keeping that reference connected allows generation and review to work against the same authoritative expectations.
How to detect when AI output drifts off-brand through an evidence-based review
The review should produce a finding for each signal category rather than a general impression that something feels off. For voice, compare the output with the structured specification for vocabulary, register, and sentence structure. Flag the exact passage and the rule it breaks. This separates a documented deviation from a reviewer’s stylistic preference. It also makes clear whether the problem concerns terminology, cadence, or the relationship with the audience.
For visuals, compare individual elements with identity tokens and their application rules. Check color proportions and use, compositional conventions, typography treatment, and logo and mark integrity. Assess mood against the approved imagery styles rather than treating technical correctness as sufficient. Record what failed for each element. A holistic verdict alone does not tell the team which choice needs correction.
For context fidelity, compare the work directly with the brief’s audience, channel, product positioning, and campaign theme. The finding should identify the mismatch between the intended work and the produced work. Across all three categories, the evidence has the same structure. It names the rule checked, the element that failed, and the specific instance in the output. Findings tied to pipeline steps help show where drift starts.
Automated QA can flag issues that can be checked before people review the work, giving creative directors more time to decide on strategy. Human editors remain the gatekeepers for product, pricing, and other high-stakes content, while judgment calls still require more than a technical pass. Clear findings make those decisions better informed without pretending every brand choice is mechanically decidable.
If image generation consistently misses compositional conventions, that pattern points to a gap in the context available at that step. The response is to improve the reference that generation and review share. Monitoring then becomes part of the infrastructure that keeps agents working from brand understanding.