Visibility and Control Over What AI Agents Publish on Brand
Shared, versioned brand rules and audit trails catch drift before it publishes.
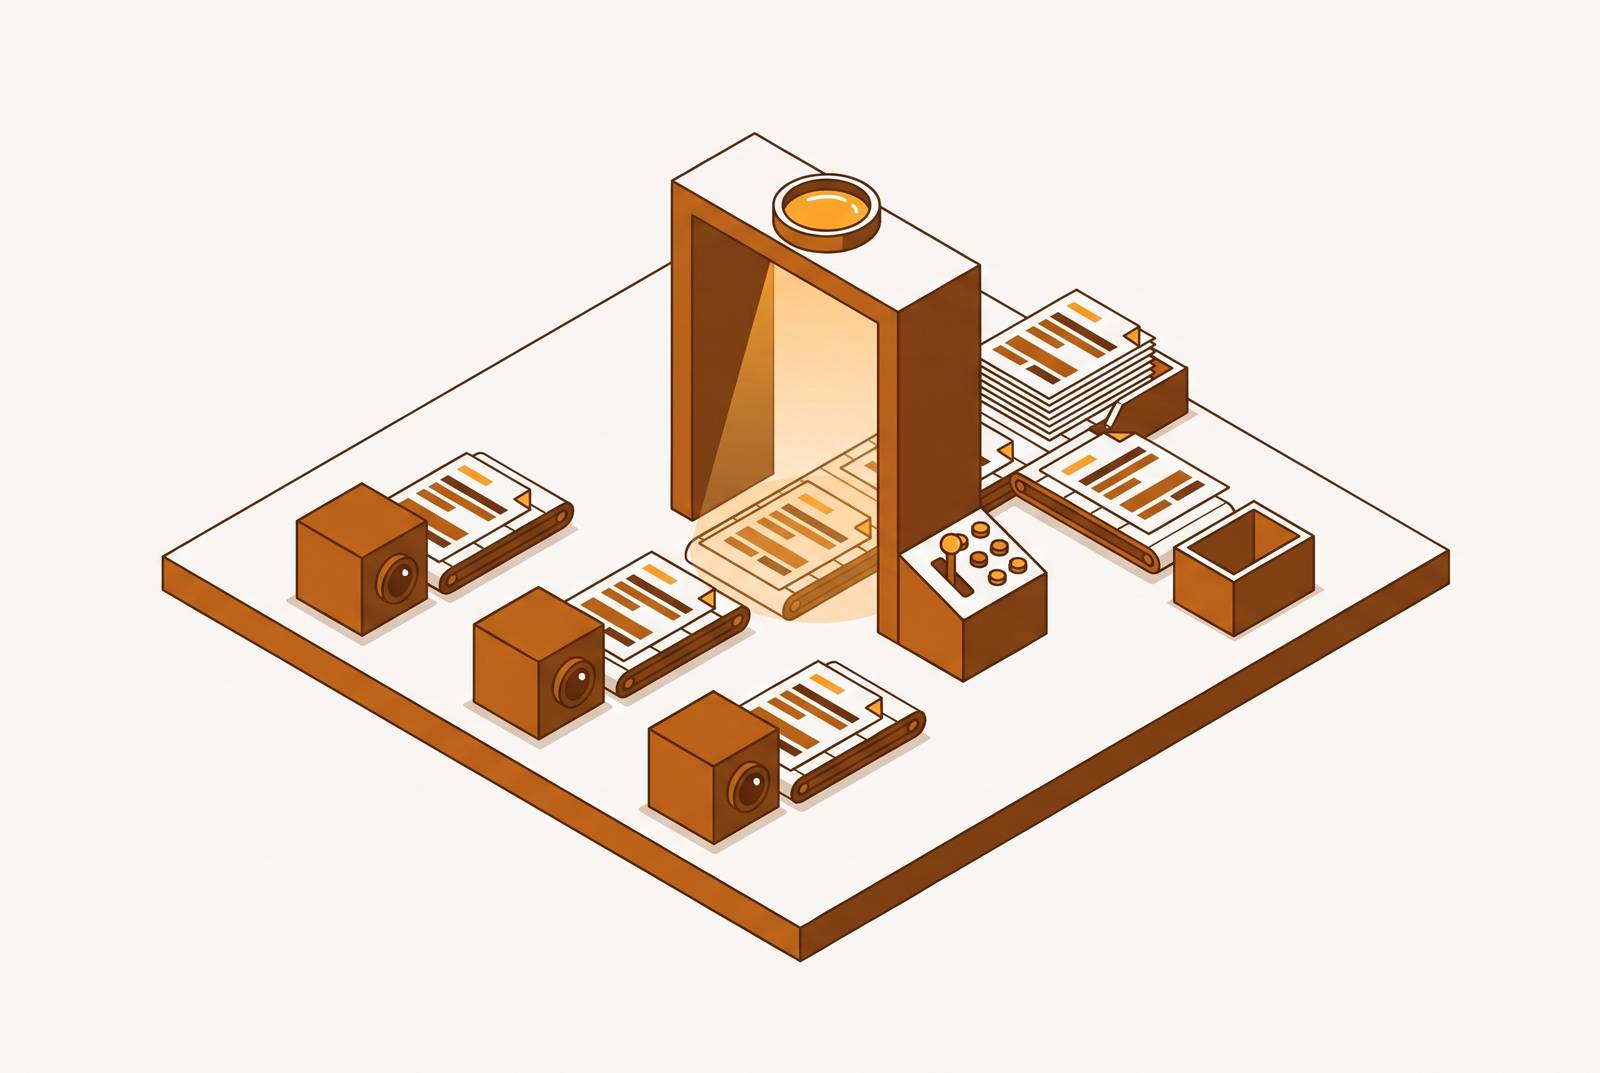
Detecting when AI output drifts off-brand requires comparing it against shared, versioned brand rules, scoring conformance, and flagging exceptions before publication. Visibility and control over what AI agents publish depend on those checks being built into the production pipeline, with an audit trail linking each output to its governing rules.
Why AI publishing creates a brand governance problem that editorial review alone cannot solve
A marketing team runs a campaign across several AI tools and receives subtly different versions of its brand. Copy changes in tone, images stray from approved colors, and claims use words that the team would not approve. Each output may look plausible in isolation. Across the campaign, however, the differences expose the absence of shared constraints.
Downstream review cannot reliably compensate for that absence because agents produce content faster than people can inspect it. In the past, each session has started without brand context that lasts, so the same prompt can give different results across models, sessions, or team members. Editors can correct individual assets, but those corrections do not establish the anchored context that subsequent generations need.
How prompt-based brand governance breaks down at scale
Pasting brand guidelines into prompts makes the rules available for a session, but it does not make them durable. Large guides can exceed context-window limits and be silently truncated, leaving users unaware that instructions have disappeared. The failure can therefore precede the first draft. A team may believe it supplied the full standard while the model works from only part of it.
Even when the guidelines fit, embedded copies create a separate maintenance problem. Once the brand changes, every prompt containing the previous rules becomes stale, with no mechanism to propagate the update. Better wording cannot repair that distribution failure. Nor does pasting a guide into a session create an auditable link between the output and the policy version that governed it.
Agencies have moved from generic experimentation through mega-prompts toward embedded branding, where rules are built programmatically into infrastructure. A more detailed instruction can improve a generation, but a pasted instruction is not a centrally managed policy that can be updated, rolled back, and inspected afterward. The missing foundation is durable, versioned, machine-readable brand context.
What machine-readable brand context actually means and why the PDF brand guide can't serve as it
A PDF brand guide explains a brand to people. A machine-readable brand artifact gives agents structured references and rules to use as they make content. A guide may make a visual identity clear to a designer without putting its colors, permitted assets, or approval conditions in a form an agent can use the same way each time.
The artifact can be understood as several connected layers. An identity layer holds visual primitives such as logos, colors, type, and shapes, while a style layer supplies visual references, image embeddings, and in-house LoRAs for image generation fidelity. Narrative rules make voice more explicit through system prompts, approved vocabulary, banned phrases, and sentence-structure patterns. Context specifies how those choices vary by channel, format, audience, and funnel stage. Governance defines approval workflows, usage rights, and versioning.
A claim needs publishing approval beyond tone, just as use of an approved logo needs permission. The artifact therefore represents both expression and constraint. To function in production, it must also be available through a live connection, such as an MCP link or canonical machine-readable URL.
How MCP changes the brand context delivery problem for connected agents
Anthropic open-sourced MCP in November 2024, so agents could query live context through a structured connection. For brand governance, the important change is when and where the agent gets its instructions. Context is available before generation as well as when the output is being corrected. An agent can query the brand’s style guide, approved asset library, and previous campaigns instead of relying on general knowledge to approximate the brand.
An MCP server gives the team control over which data the model sees, how it is structured, and how the agent interacts with it. That replaces crawl-and-parse retrieval with an interface the team controls. Connected agents can draw from the same anchored, versioned source. Structured access also avoids relying on a large pasted guide whose rules may be silently dropped.
The connection still needs its own governance. Stacklok’s December 2025 survey found that security concerns were the top obstacle to MCP adoption among the technical leaders surveyed. Server access controls must be part of the brand governance design, because teams need to control who can use the shared context. MCP provides a delivery mechanism that requires permissions and publishing policy.
The agent architecture that enforces brand rules inside the production pipeline
A fleet of specialized agents can operate behind a shared governance layer, with checks embedded in the flow of production. The Brand Guardian Agent illustrates this pattern. Its sole purpose is to evaluate a draft against stylistic and compliance guidelines, returning it to the creator agent for revision before a human sees it.
For voice, the evaluator needs more than an instruction to sound consistent. For reliable pattern recognition, the evaluator needs a large body of long-form brand content or enough short-form examples. Visual production has related controls. Custom LoRAs can support generation in a client’s product or artistic style, while post-generation correction agents can detect and correct colors against official Pantone or hex codes before human review.
Validation, however, does not grant every output equal autonomy. Risk tiering defines that boundary in advance. Social captions have different stakes from pricing pages or regulated claims, so low-risk content can publish after automated validation while high-risk content waits for a human to approve it. Claims, pricing, and regulated content can be designated as requiring sign-off regardless of agent confidence.
A draft can conform stylistically and still require approval because of what it says. Versioned prompts and policies, traceable decisions, and rollback mechanisms support that separation by making the governing rules inspectable and correctable. The architecture must control both how content is produced and which decisions an agent may make autonomously.
How do teams detect when AI output drifts off-brand, and why are audit trails non-negotiable?
A publishing system must be able to explain its decisions. Accountable automation requires an observable record establishing why an output passed and which standard governed it. Each piece needs an inspectable chain connecting the person who briefed the agent, the applicable brand rules, and the review or approval that followed.
Voice signals include departures from approved vocabulary, use of banned phrases, and deviations from prescribed sentence patterns. Visual signals include non-compliant logo placement, color palettes, and design templates. Compliance signals include messaging that violates the applicable rules or content that requires human sign-off.
A practical audit system connects those checks to conformance scoring and escalation. Dashboards track brand alignment rates, drift scores, and KPI impact across channels, while confidence scores and threshold triggers flag outputs that a human needs to review before they are published. The audit trail supplies the explanation behind the score. By linking each output to versioned prompts and policies, it makes a post-publication question such as “why did this say that?” answerable and supports rollback when a rule change produces unexpected results.
How the human role in AI brand publishing shifts from production to instruction and audit
Humans set the standards that automation must follow. Their upstream work includes writing the machine-readable artifact, setting risk tiers, making taste judgments, and specifying escalation triggers. Those decisions shape every output that follows.
The audit role is equally specific. People check the system’s output against brand standards, use observability to spot drift before it builds up, and use what they find to update policy. They also handle judgment escalations for claims, regulated content, and high-stakes launches. These are distinct responsibilities, even when the same team performs them, because policy design, system inspection, and publication approval answer different questions.
Google’s Think with Google recommends mapping one important workflow with explicit human-AI handoffs. That map identifies who or what commissions, performs, checks, and approves the work, including what happens when an output is wrong, weak, or incomplete. Zalando’s Met Gala campaign illustrates this connected operating model. The team linked trend signals, product relevance, visuals, and editorial review to publish the day after the gala. Roland Butler, head of product, described it as “building a whole creative system around those teams, maintaining their agency and their creative freedom, and allowing them to respond faster and better.”
What agencies and multi-brand teams need differently from single-brand operators
Agencies must prevent one client’s context from contaminating another’s. A shared workspace containing different voice rules, visual systems, and compliance constraints makes that separation an infrastructure requirement. Each client needs a separate, versioned brand artifact that can be updated and audited independently. A change to one client’s standards must not become another client’s instruction.
Multi-brand and multi-market work can require agents to check several applicable rulesets simultaneously, assessing logo placement, palettes, messaging, and templates against the right client standards. The distinction is between shared execution and shared identity. Agents may perform similar tasks across clients without treating their brand context as interchangeable.
Proprietary data adds another boundary to manage. Custom MCP servers are a good fit when product catalogs, loyalty databases, or internal pricing engines give a business its edge and no off-the-shelf server exists. Agencies can also normalize feeds from multiple marketplaces to give agents a single interface for cross-channel work. Those connections extend the production system without removing the need for client-specific access and governance.
Solving these requirements changes the agency deliverable. Research, rollout, and monitoring agents can support a monthly brand-stewardship retainer, turning consistency monitoring into an ongoing service. Adobe Brand Visibility, announced June 2026 with general availability in August 2026, shows how platforms in this category are taking shape. It brings together Semrush’s AI visibility intelligence and Adobe’s agentic content optimization, which draws on brand context.
The design principles that make brand governance a pipeline property rather than a process step
The design test is whether a brand change becomes a system event or another request for people to update their prompts. Teams need one authoritative, versioned source that connected agents use automatically, whether the connection runs through MCP or an API-integrated product. Local copies weaken that authority. A machine-readable artifact serves this purpose, while the human-readable guide continues to explain the brand to people.
Depending on content type and risk, automated validation is sufficient or human sign-off is required. Evidence must exist before the content ships. The audit trail is a first-class output of the pipeline, and continuous conformance scoring and anomaly detection make oversight an ongoing operation.
For teams without engineering resources, this model need not mean building every component themselves. Brand-context infrastructure is becoming a managed service that teams can add, much as they connect to a CMS. When buying a service, teams need to check that it offers shared context, gates it can enforce, and decisions they can inspect, along with convincing drafts. Brand context belongs in the same category as a CMS or a design system, as critical infrastructure that governs what the organization publishes.