Why Prompt Stuffing Breaks Down at Team Scale
Shared brand rules beat pasted prompts as teams scale.
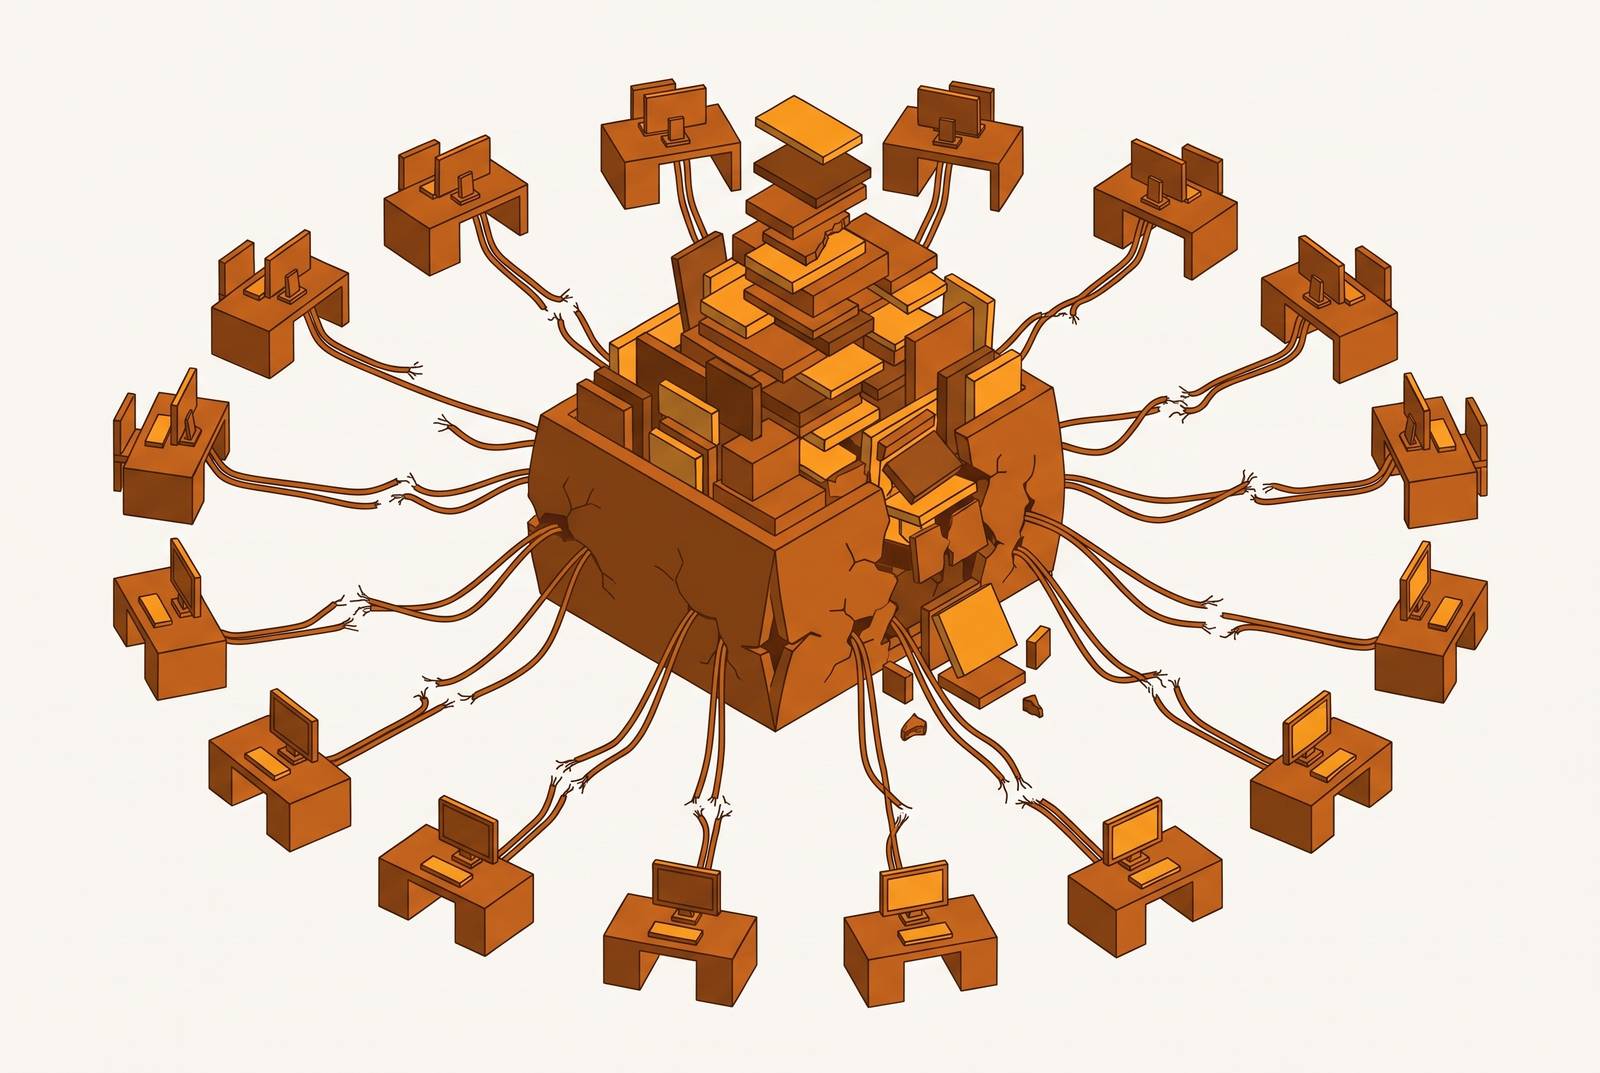
Prompt stuffing breaks down at team scale because brand consistency depends on shared state. Drift is bound to happen when context windows have limits, people read the rules differently, and each uses a separate copy of the guidelines. Addressing these constraints requires brand infrastructure that connects authoritative rules, task-specific briefs, and evidence-based review.
Why pasting brand context into every chat window is a structural dead end
Prompt stuffing makes each chat session responsible for reconstructing the brand. It means copying a brand guide, voice document, or guidelines block into the top of a session before making a request. The intuition is reasonable. If the model receives the rules before it receives the task, it should produce work that follows those rules. But the arrangement makes consistency depend on what each contributor supplies to each session, rather than on a shared authority available to the whole team.
That dependency is the actual failure mode. A well-written prompt can guide one response, but it cannot give context unlimited space, settle how each contributor reads the rules, or keep everyone’s copies up to date. These are separate constraints, so improving one leaves the others intact. Tool choice and individual effort do not remove them. When all three operate together across a team, brand drift is the expected consequence of the workflow.
How context windows silently deprioritize brand rules as a session grows
A pasted brand guide competes with the task for the model’s effective attention. Context windows are finite, and information within them does not exert equal influence simply because it is present. Position affects how reliably instructions shape the response. A lengthy document can therefore contain the right rules while placing some of them where they are less likely to influence the output.
Liu et al.’s 2024 study “Lost in the Middle” documents a U-shaped pattern in which models favour information at the beginning and end of a prompt while underweighting the middle. This complicates the simple claim that recent instructions always win. Early placement can help, but rules buried within a long guide remain disadvantaged relative to content at either extreme. As a multi-turn session grows, the model follows earlier brand context less reliably in later outputs, while the current request competes for attention.
A team may improve placement and reduce unnecessary material, yet the underlying workflow still asks transient session context to perform the work of persistent brand governance.
What happens when fifteen contributors each interpret "conversational" differently
Even an unlimited context window would not resolve ambiguity in the rules themselves. Fifteen contributors can use the same word, “conversational,” while expecting different writing from it. None needs to be plainly wrong. The inconsistency appears across the body of work, where individually defensible choices fail to form a recognizable voice. Copying identical language into every session does not make that language precise.
Traditional brand control depended partly on a production bottleneck. A small team or agency developed shared judgment through repeated work and editorial feedback, so brief descriptions could rely on experience that remained unstated. AI expands production beyond that shared history. More contributors across teams and regions can generate brand-facing work through different tools, without the repeated calibration that once made implicit rules usable.
The distinction is between an adjective and an instruction. “Sound friendly and professional” asks the contributor and model to interpret a tone, while rules covering contractions, second person, sentence length, banned phrases, and claim constraints make the intended behaviour explicit. Without that translation, models tend to write like the rest of the industry, using generic, slightly breathless marketing language. The brand loses specificity even when the prose remains competent.
Why no shared source of truth means every update creates a new inconsistency
Perfect interpretation would still leave the problem of change. Brand guidelines change with new positioning, updated messaging, seasonal campaign rules, and new names for products. Under prompt stuffing, each change requires contributors to replace or revise their own saved context. Updates spread unevenly and slowly. The workflow provides no mechanism that makes the authoritative change available automatically wherever generation happens.
A saved prompt can therefore still make sense on its own even after it is out of date. Another contributor may have the latest messaging but an older voice block, while small edits to their own copies move those copies further from what the rules were meant to say. Prompt stuffing itself supplies no audit trail linking an asset to the version of brand context used to produce it. When quality shifts, the team cannot reliably distinguish a changed rule from an outdated copy or an ungoverned edit.
Longer windows would not synchronize updates, and more disciplined contributors would still have to maintain distributed copies manually. As those copies are reused and revised, the team no longer has one operational definition of the brand. It has competing versions whose authority cannot be established from the finished work.
Why better prompts cannot solve a structural problem
Structured prompting offers a serious improvement over ad hoc instructions. Layered voice blocks, channel-specific constraints, versioned templates, and shared evaluation criteria can produce meaningfully better outputs. Clearer prompts reduce avoidable ambiguity. They also keep lasting brand requirements separate from the current request, so contributors do not have to piece them together from memory each time.
The limit appears when distribution remains manual. A well-designed template sitting outside the agent still depends on someone selecting the right version, maintaining it, and placing it in the session. Versioning the master template does not update the copies people on the team have already saved. Better organization can reduce inconsistency without removing the shared-state problem that produces it.
Guidelines and prompts also perform different jobs. Guidelines explain the brand’s intent, while prompts turn that intent into instructions for a particular response. Both are useful, but neither becomes a shared, current authority merely by being well written. If every contributor must reconstruct the connection, the system still relies on individual compliance at every use.
Structured prompting should continue, with the prompt treated as one part of the entire control system. AI exposes brands whose operating rules exist only in people’s heads or inconsistently maintained files, and sharper wording cannot substitute for a common source that agents actually use.
What brand infrastructure actually means in an agent-native workflow
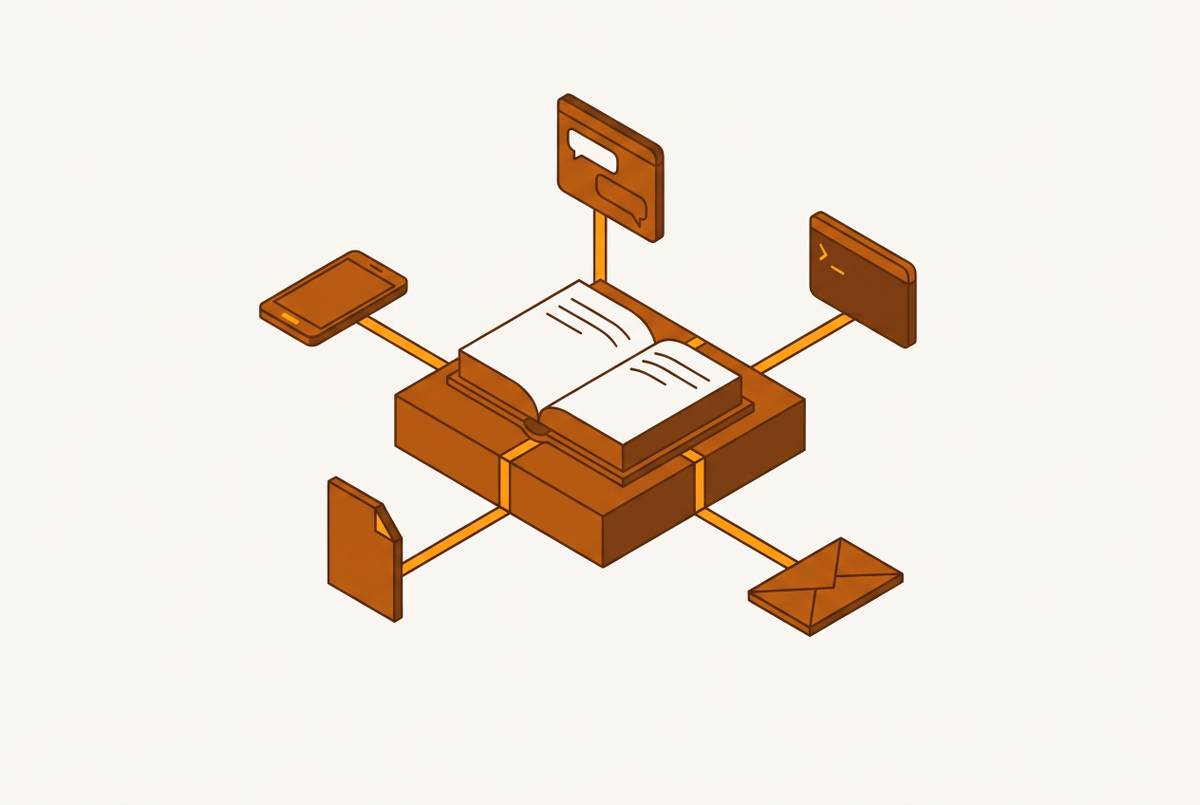
Brand infrastructure is a single, versioned, machine-readable source of context that every connected agent draws from. Its authority does not depend on a contributor remembering to paste it. Changes are tracked in one place, and agents retrieve the current state.
Each property addresses a different failure. Centralization replaces distributed files with one authoritative source, while versioning makes changes traceable and supports their propagation. Machine-readable rules translate creative intent into explicit behavioural constraints. When agents share those rules, the brand definition does not have to be built again for each tool and session.
That translation is more demanding than storing a traditional guide. A description such as “sound confident but not arrogant” depends on judgment that the instruction set must express through sentence structure, prohibited language, and claim constraints. The purpose is to reduce interpretive latitude where consistency requires a clear rule.
Versioning works much as it does for code. A brand change is made once in the shared context layer, and connected agents retrieve the current version on their next query. This architecture belongs before agent deployment, because retrofitting it after drift accumulates leaves the initial workflow without a common authority.
How MCP changes where brand context lives relative to the agent
MCP standardizes the interface between models and data sources, replacing the need for a bespoke connector for every pairing. For brand context, that means a single server can provide the shared rules to connected agents across the stack. The context remains outside any individual conversation. Its availability follows the agent’s connection to the source rather than the contributor’s habit of pasting a document.
This changes the location of authority. Voice, visual, and messaging rules can live in one brand-context server, so teams no longer have to keep separate blocks up to date across tools. Each connected agent queries the same source for the context it needs. When the brand changes, the server is updated once, and subsequent queries retrieve the current version without requiring contributors to revise their personal prompts.
The architectural gain is shared access. MCP addresses the connection and propagation problem that manual copying leaves unresolved. Making vague adjectives available does not turn them into clear rules, so they still need to be translated into machine-readable instructions. The finished work still needs review even when agents have access to the rules.
Why multi-agent systems make unresolved brand context exponentially more damaging
Disconnected context causes more trouble in multi-agent workflows than in a single chat session. For much of 2024–2025, an agent was often a single assistant looping over tools. As specialist agents work together, they bring explicit routing, shared state, and governance to a series of tasks. Brand interpretation now affects the handoffs as well as the individual outputs. Scale reveals what was already structurally unsound.
Without persistent shared context, each agent starts from its own interpretation. A copy agent, an image-briefing agent, and a review agent can each follow locally plausible rules while producing a result that is inconsistent as a whole. Their differences compound across pipeline steps, because later work depends on choices already made under a different understanding of the brand.
Transient memory adds another source of divergence. A detailed guide supplied earlier cannot serve as a durable guarantee that an agent’s later work will remain specific to the brand. With prompt stuffing, a policy change also means updating the prompt for each agent that takes part. A shared context layer instead lets them retrieve the same updated policy from one source.
If the review agent uses a different brand interpretation from the production agents, the workflow lacks a common standard for judging its own output. Correcting an individual prompt cannot reconcile the entire chain.
What consistent AI output actually requires before content is reviewed or shipped
To keep output consistent, teams need shared context, task-specific briefs, and review against brand criteria they can trace. Each performs a distinct job. Shared context establishes the authoritative rules, but those rules still need to be translated into constraints appropriate to the work. A homepage, paid ad, campaign email, and launch deck cannot all receive an undifferentiated global guide and be expected to express the brand appropriately.
The layered model separates a stable brand foundation, a semi-stable channel layer, and a dynamic task layer. This separation keeps a task instruction from quietly becoming a general brand rule, or a channel constraint from being applied where it does not belong. Structured prompting remains useful within this architecture. Its role is to express the brief against shared context, rather than to recreate the entire brand from a saved block.
Review then tests whether the system followed that context. Specific checks against specific rules, with a record of what passed and what did not, provide evidence that an intuitive judgment cannot. The broader concern is recurring drift. Those patterns show whether generation remains aligned with the authority it is supposed to use.
AI produces the first pass from shared context and the task brief, while a person with brand authority reviews it against traceable criteria before anything ships. The complete infrastructure therefore extends from the source of the rules to their application and verification. Brand consistency becomes a governed property of the workflow.