Giving AI Agents a Living Brand Reference They Check Before Every Output
Agents need a versioned brand source they query before every output.
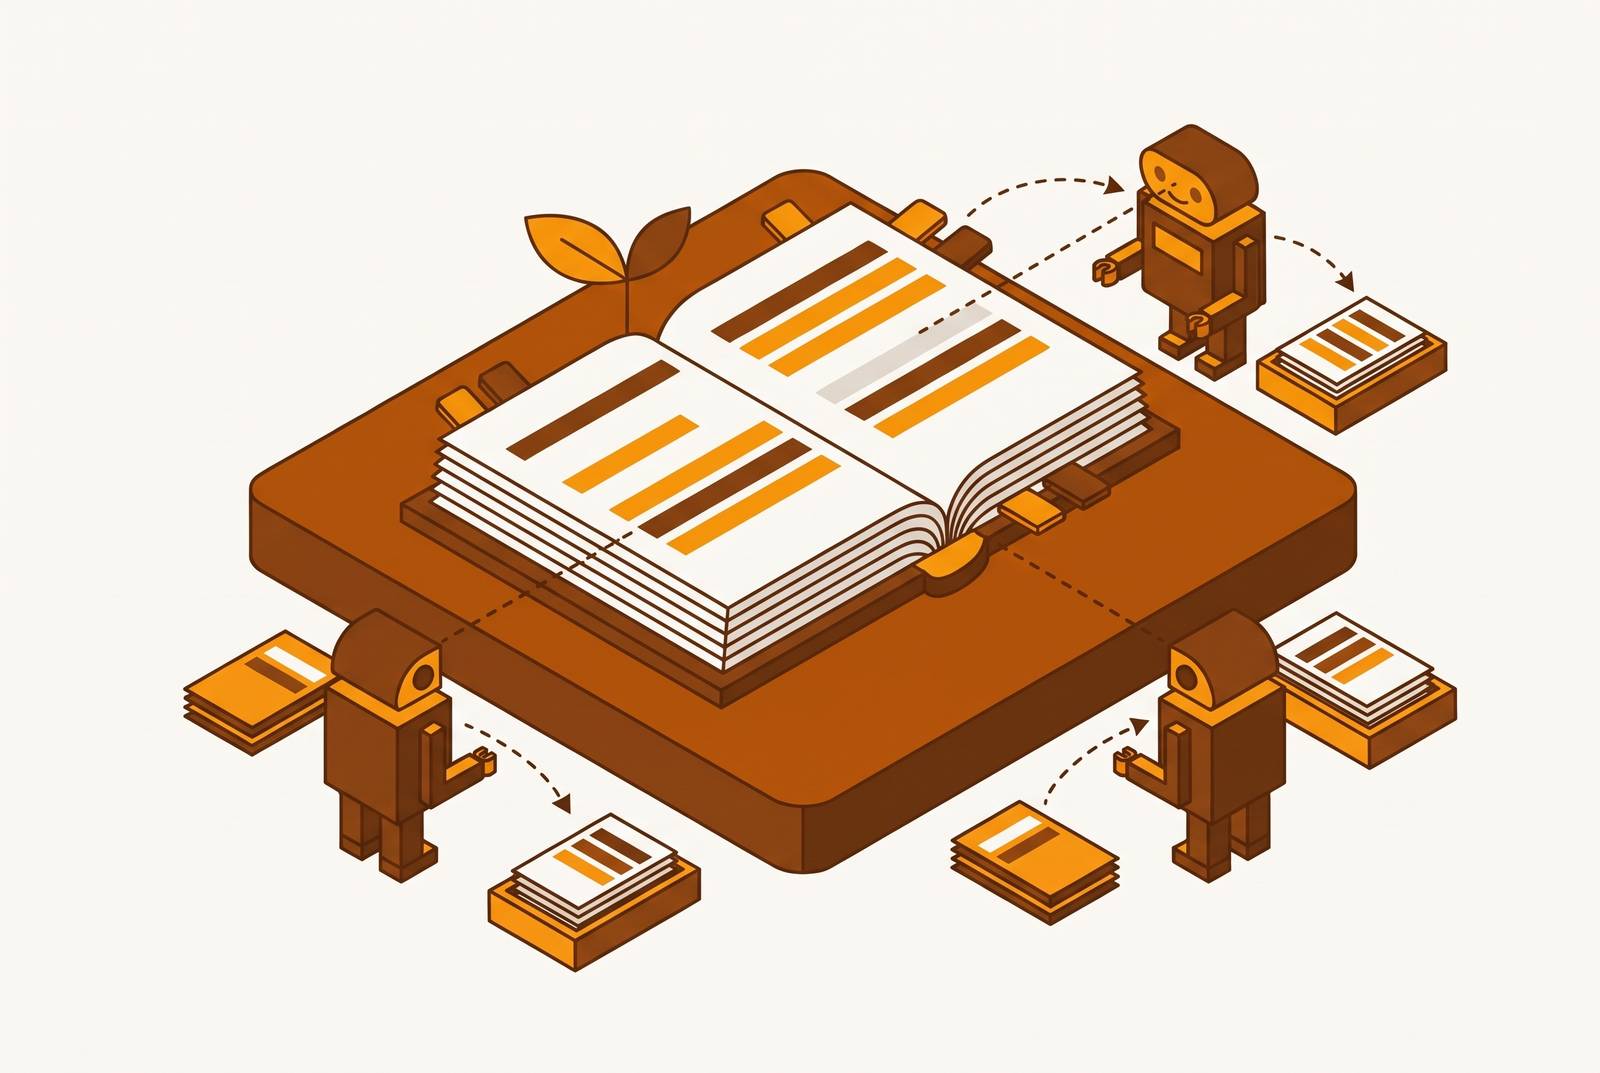
Detecting when AI output drifts off-brand requires comparing finished work against explicit rules for voice, terminology, color, typography, logos, and imagery, with evidence for each deviation. A living brand reference gives agents persistent, versioned context they can check against the work before each output. Reliable brand consistency comes from connecting that reference to task briefs, automated review, and human approval, rather than relying on reminders inside individual prompts.
Why brand guidelines stored as documents fail when AI agents are doing the work
Brand documents and AI agents operate differently. A guide written for people assumes that someone will read it, interpret its examples, and retain its meaning while working. An agent operates from context loaded at runtime. A rule can therefore exist in an approved document without being present when the agent generates an asset. The failure is architectural.
The bottleneck model of brand control depended on a small team or agency making the content, but generative AI lets everyone produce work simultaneously. Each person writes prompts in a different way, pulling the brand in slightly different directions. The AI design agent analysis identifies outdated PDF guides, old templates used by non-designers, and rushed compromises for platform specifications as structural causes of inconsistency. These problems precede generation and shape what agents receive.
Longer prompts do not resolve the underlying disconnect. Mega-prompts are inefficient, difficult to maintain across dozens of clients or team members, vulnerable to context-window truncation, and a source of data security exposure. They make people piece together brand guidance by hand each time, so each prompt is another place where the rules can differ. There is no persistent connection between the brand knowledge and the agents.
What a living brand reference actually contains, translated for machine consumption
A living brand reference expresses identity as machine-operable constraints. Its rules are specific, behavioral, and organized so that an agent can retrieve the part relevant to its task. For voice, that means stating whether contractions are allowed, whether copy uses second person, how long sentences may be, which phrases are banned, and which terms are preferred. “Sound friendly and professional” does not supply a model with comparable criteria for compliance.
Colors become hex or Pantone values rather than names, while typography specifies font family, weight, and size ranges. Logo guidance sets out the minimum clear space and which lockups are approved. Imagery guidance distinguishes photography tone from illustration style, giving review something more exact than a general request to look on-brand. The same analysis maps these brand elements to checks and actions when an asset violates a rule.
Design tokens make visual rules enforceable by machines. A token represents a value such as color, spacing, or type, so updating it changes the rule applied to future assets. Content needs an equally structured foundation, including consistently tagged product names, audience definitions, legal claims, and approved examples. Inconsistently managed material gives agents inconsistent inputs even when the generation process itself is orderly.
The reference must also support different roles. A copywriting agent needs rules for voice and terminology, while a visual agent needs design constraints for the work it is making. Their slices differ, but their authority must not. Both should come from one certified source, stored in an accessible, permission-aware location connected to assets and workflows. This gives people and systems a common reference without requiring every task to consume every rule.
How agents consume brand context at the moment of a task, not before it
Brand context that is available somewhere but never queried is absent in practice. A context-access protocol gives an AI application a way to access context from connected systems through a server. For brand work, that connection lets an assistant retrieve guidance when a task requires it, rather than depend on someone pasting the guidance into a conversation.
Brand guidelines in a digital asset management system can become accessible to a writing assistant, while campaign history can inform a planning agent. A Notion or Google Drive MCP server lets Claude pull a brand voice profile and content calendar by name. The context does not have to be rebuilt manually. Early enterprise adopters of MCP servers include Stripe, Linear, Sentry, and Vercel, as well as HubSpot, Salesforce, and Notion, providing integration patterns that brand infrastructure teams can follow.
A REST API provides another delivery path. It embeds the same brand context into a team’s own product rather than making it available through an external agent connection. The choice depends on whether the agent is external, such as Claude, ChatGPT, Cursor, or Codex, or internal. Both paths should get their context from the same reference.
The delivery unit is a task-specific brief. Instead of passing the entire reference into every prompt, the system supplies the logo, typography, color, imagery, and voice rules that the current output requires. Scoping prevents context overload and keeps instructions precise. It also preserves the distinction between the persistent brand source and the temporary instructions for a particular piece of work.
Why multi-agent pipelines break without a shared brand source
A copywriting agent and a visual agent can each produce plausible work while creating an incoherent result together. Agent memory is session-scoped, so neither automatically inherits the other’s context. Orchestration can line up their tasks without settling which brand rules both should follow. For brand consistency, the primary failure is therefore the absence of shared context.
The architectural response is to separate instructions, task state, memory, knowledge, tools, and governance. A shared context repository then gives each agent a role-specific slice of the same certified brand truth. The reference holds persistent state. A headline and an image can consequently be checked against the same source, with the relevant voice and visual rules applied to each. When context is siloed per agent, there is no common basis for that check.
This distinction is especially important for agency pipelines. Copy and visual production for a client need different instructions, but neither should define its own version of the client’s identity. Founders and small teams face the same problem through people. Without shared machine-readable rules, each team member’s prompts pull the brand in a different direction across dozens of daily outputs.
Keeping the brand reference current as an operational discipline
A shared source can also become a shared error. If its guidance is stale, connecting more agents spreads that outdated guidance. The same failure already appears when agencies and freelancers work from PDF guides that are months out of date. Moving those rules into a system does not, by itself, make them current.
Brand governance therefore requires versioning and change propagation. Templates need version control, a record of who changed what, and the ability to roll back. The same analysis describes a token-based styling model where changing a design token automatically changes every asset made from then on. That links maintenance to production rather than leaving it as a separate documentation task. The reference is reliable only when its current version reaches the agents using it.
Propagation distinguishes infrastructure from a stored file. When the brand changes, connected agents should receive the new version without each team manually revising its prompts or templates. The update happens once at the source. Maintaining that connection is an operational discipline because the source must remain authoritative through change. Otherwise, a centralized reference reproduces the very fragmentation it was meant to remove.
How to detect when AI output drifts off-brand before it ships
Static templates can constrain layout, but they cannot check images against the brand’s photography style or headlines against its voice guidelines. Automated brand review evaluates the finished work against those rules. It is not a spell-check. The review compares the asset with the same reference used for generation and produces evidence for individual checks.
Color checks compare hex values with the primary and secondary palettes, while typography checks compare font family, weight, and size with approved ranges. Logo checks examine minimum clear space and approved lockups. Imagery checks look at photography tone and illustration style, and layout checks look at grid alignment and margins. Copy checks look for deviations in headline style, CTA phrasing, and terminology.
The same analysis maps those checks to different responses. Colors can be corrected or flagged, typography can be replaced with approved fonts, and incorrect logo usage can be rejected for correction. Imagery review can suggest other images that are on-brand, while layout correction can snap work to the approved grid. Copy review flags off-brand language. Each response should identify the rule involved so that a team can improve the asset or its brief.
Those checks form a practical audit system. Compliance scores per asset make conformance measurable, while evidence tied to specific rules explains what needs attention. A score without that evidence cannot tell a reviewer whether the problem is terminology, logo spacing, or visual treatment. Revision rates and time-to-approval then help teams see how well the workflow works after the first check. The audit is useful because its conclusions are traceable.
AI tools approximate color rather than guarantee exact values, so the recommended agency workflow includes a designer’s post-generation review and correction to official Pantone or Hex codes in an editor. Tiered approval assigns automated checks to colors, file specifications, and accessibility. Designers check batches of standard social and advertising assets, senior reviewers take on flagship assets, and stakeholders sign off on legal or regional requirements.
Typeface’s brand management guide describes its Brand Agent as checking images and copy against the Brand Kit before publishing, flagging deviations in tone, terminology, and visual treatment. Typeface customer data says a Fortune 500 insurance provider that used this approach cut the time it took to make creative work significantly while keeping human review. Human judgment remains part of the system. The AI brand messaging guide and brand strategy execution work identify it as a primary trust signal for audiences, particularly where voice, audience response, and positioning require interpretation. The workflow is AI drafts, human directs.
The operational model of one brand source, every agent, every output
In operation, the workflow begins with a team adding its brand from a website, brand guide, or files. Agents connect through MCP, or a product integrates through an API, and each task generates a scoped brief. The agent produces work from that brief. Automated review compares the result with the reference before a person approves and publishes it. Brand knowledge is not re-entered, re-pasted, or rebuilt for each task.
Production and governance can have distinct roles. In the Brand Guardian Agent pattern, a dedicated compliance agent reviews creative agents’ outputs before they reach a human reviewer. For agencies with more than one client, the infrastructure works separately for each brand, and a multi-brand management layer keeps each client’s context apart from the others. Each connected agent must use the reference for the client whose work it is doing.
Performance then becomes measurable against explicit criteria. The same analysis says teams make significantly more assets per designer-hour while keeping brand compliance scores at the same level or raising them. Compliance scores, revision rates, and time-to-approval provide different views of that result, covering conformance, rework, and review speed. Those measures become interpretable because the rules are explicit and versioned. The operational test is whether every output can be traced to the brand guidance used to produce it and the checks applied before publication.